The Structural Mechanics of Compute Denial
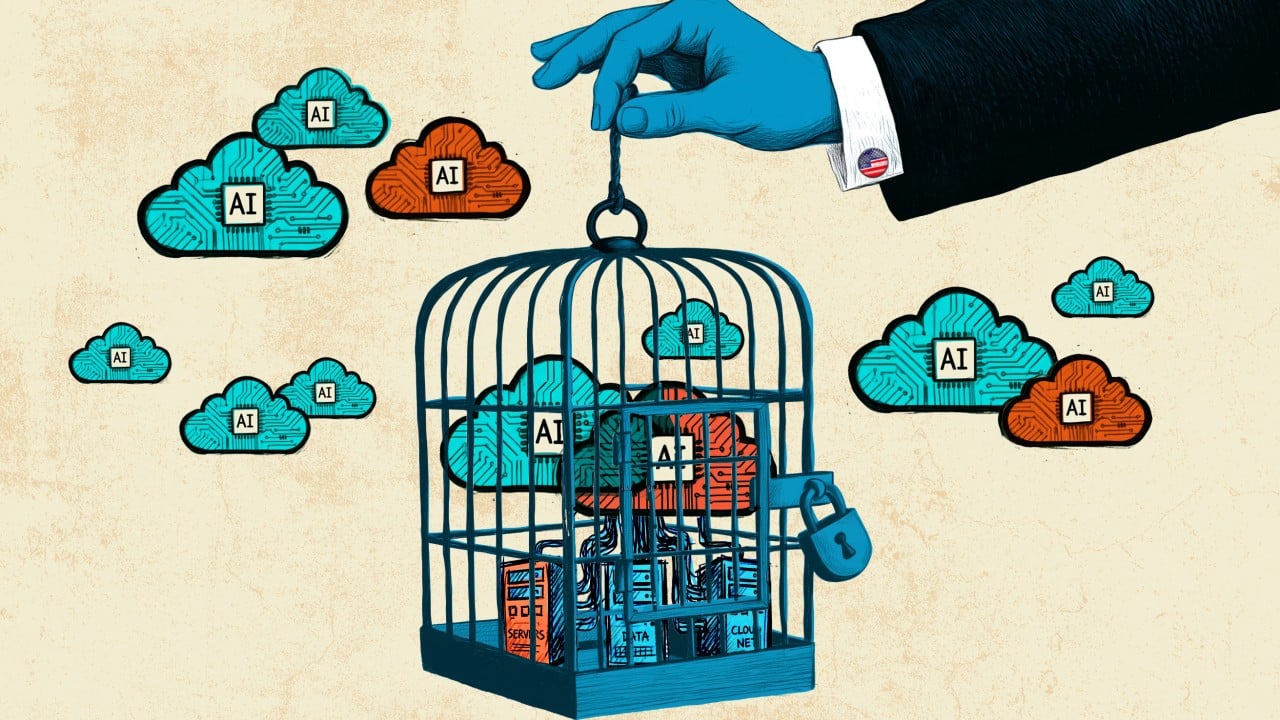
The escalation of export controls governing advanced computing infrastructure marks a structural turning point in international technology policy. Initial regulatory frameworks focused exclusively on physical customs checkpoints, targeting the export of discrete semiconductor components such as advanced graphical processing units and tensor processing units to mainland entities. However, the fungibility of digital services created an immediate vector for arbitrage: remote-access cloud computing. When physical silicon cannot cross a border, compute capacity accessed via remote data centers in third-party jurisdictions provides an operational workaround.
Regulators addressing this loophole face a fundamental operational challenge. Cloud infrastructure is inherently borderless in its consumption model. A research laboratory in Beijing can train a large language model utilizing high-performance clusters hosted in Southeast Asia, Europe, or the Middle East, communicating over high-speed fiber-optic links with minimal latency penalties for asynchronous training batch jobs. The policy pivot by regulatory bodies to restrict remote access to advanced AI chips via Infrastructure-as-a-Service providers fundamentally alters the economics of artificial intelligence development across global markets.
To understand how China's artificial intelligence sector adapts to these converging pressures, one must deconstruct the problem into three primary analytical variables: compute availability, algorithmic efficiency, and domestic hardware substitution. Each variable dictates a specific survival vector for domestic operators, shaping short-term training economics, capital expenditure thresholds, and long-term architectural design choices.
The Arbitrage of Offshore Cloud Infrastructure
The historical reliance of Chinese technology firms on overseas cloud capacity emerged as a direct response to physical silicon export limits. By renting server instances housed in third-party jurisdictions, enterprises bypassed domestic hardware shortages. This operational model depended on foreign colocation facilities maintaining unencumbered access to advanced semiconductor hardware supplied by dominant Western manufacturers.
The mechanics of offshore cloud rental involve high capital expenditure and complex corporate structuring. Domestic firms establish foreign subsidiaries, partner with regional data center operators, or utilize intermediary brokers to provision clusters of advanced processors. These clusters execute multi-node distributed training jobs, streaming intermediate checkpoint weights back to domestic research headquarters over encrypted channels.
As administrative scrutiny expands to target third-country data center access, this offshore arbitrage mechanism encounters severe friction. New licensing requirements, rigorous Know-Your-Customer mandates for cloud users, and proposed location-tracking hardware requirements drastically raise transaction costs. When offshore rental costs scale exponentially due to compliance overhead and scarcity premiums, the financial model breaks down for smaller market participants. Only heavily capitalized enterprises can absorb these compliance and rental expenses, driving rapid market consolidation among state-backed national champions.
The regulatory tightening in third-country data centers forces firms to confront the permanence of their operational constraints. Renting foreign compute is a diminishing asset class. As compliance nets tighten around popular transit hubs in Southeast Asia and the Middle East, enterprises must redirect capital away from temporary cloud rentals and toward domestic infrastructure resilience.
Algorithmic Compression and the Shift in Training Economics
Faced with constrained access to raw floating-point operations per second, Chinese research groups are forced to alter the economic equation of model training. When hardware scaling laws hit a hard ceiling imposed by regulatory restrictions, optimization must occur entirely within software architecture and data efficiency.
Traditional large-scale model training relies on brute-force scaling: increasing parameter counts alongside training token volumes while maintaining dense transformer architectures. Under strict hardware rationing, this strategy becomes economically unviable. Domestic labs have consequently accelerated research into architectural efficiency, shifting focus toward sparse mixture-of-experts designs, selective state-space models, and extreme quantization techniques.
Mixture-of-experts topologies decouple active parameter count from computational cost per token, allowing models to scale capacity while activating only a fraction of their total parameters during forward and backward passes. This architectural choice reduces the memory bandwidth bottleneck that typically cripples training efficiency on older or lower-bandwidth hardware generations. Furthermore, algorithmic innovations in low-bit training—such as sub-8-bit floating point representations—mitigate the memory capacity constraints inherent in restricted hardware environments.
The economic trade-off is clear: engineering complexity replaces capital expenditure. Designing, debugging, and stabilizing highly sparse or unconventional architectures requires significantly higher human capital and experimental iteration cycles. The constraint shifts from hardware acquisition budgets to elite engineering talent density. Labs that master architectural compression achieve high model performance per watt and per FLOP, while those reliant on brute-force iteration face prohibitive computational costs.
Domestic Semiconductor Substitution and Packaging Constraints
While software optimization mitigates short-term compute deficits, long-term viability requires a domestic semiconductor manufacturing base capable of producing competitive accelerators. China's domestic semiconductor sector faces formidable structural hurdles, particularly in lithography, yield rates, and advanced packaging.
Advanced AI accelerators require extreme transistor densities and high-bandwidth memory integration. While domestic foundries have made notable progress in mature and intermediate process nodes, extreme ultraviolet lithography equipment remains inaccessible due to multilateral export restrictions. Domestic chip designers must rely on older deep ultraviolet immersion lithography, utilizing multi-patterning techniques to achieve comparable feature sizes. Multi-patterning introduces severe cumulative overlay errors, depressing wafer yields and driving up unit production costs.
This manufacturing reality forces a reliance on alternative design paradigms. Rather than attempting an immediate, direct clone of leading-edge Western architectures, domestic designers focus on cluster-level interconnect efficiency. By clustering numerous smaller, lower-yielding domestic processors using proprietary high-speed interconnects, engineers attempt to match the aggregate throughput of monolithic advanced chips.
Beyond raw silicon fabrication, advanced packaging represents a critical operational bottleneck. High-performance accelerators depend heavily on 2.5D and 3D packaging technologies—such as chip-on-wafer-on-substrate integration—to connect processor dies with high-bandwidth memory stacks. Domestic capacity for advanced packaging is expanding, but throughput and reliability lag behind global market leaders.
As a direct result of these packaging limits, domestic accelerators produced by firms like Huawei operate under severe supply volume constraints. Even when functional parity is approached in specific benchmark tests, the total volume of domestically fabricated silicon falls far short of aggregate domestic demand from search giants, enterprise cloud providers, and specialized AI laboratories.
Capital Allocation and State-Directed Subsidies
The financial burden of navigating export controls and domestic substitution is largely underwritten by state-directed capital allocation. Market-driven venture capital models struggle to sustain multi-year, capital-intensive silicon and algorithmic substitution efforts without immediate paths to commercial profitability.
Local municipal governments and national science funds have stepped into this vacuum, financing the construction of regional intelligent computing centers. These state-backed facilities acquire whatever compliant or domestically produced hardware is available, offering subsidized compute time to local startups and research institutions. This intervention prevents the immediate market starvation of smaller AI entities that cannot afford offshore cloud arbitrage or scarce domestic silicon allocations.
However, state-directed capital deployment introduces its own inefficiencies. Centralized allocation models often prioritize volume and political visibility over rigorous commercial performance metrics. Subsidized compute hubs risk misallocating resources toward obsolete hardware architectures or redundant software stacks, creating pockets of localized overcapacity alongside acute shortages of high-performance training throughput.
The interaction between state subsidies and commercial survival creates a distinct market dynamic. Enterprises must balance commercial market demands with the compliance and reporting requirements tied to state-backed compute access. This dual-track operation increases administrative overhead but provides a vital financial cushion against hardware scarcity.
The Bifurcation of Global Artificial Intelligence
The structural friction generated by cloud restrictions and export controls ensures the permanent bifurcation of the global artificial intelligence ecosystem. Rather than total exclusion, the outcome is a partitioned operational environment defined by differing cost functions and efficiency metrics.
In the unrestricted sphere, development continues along the traditional trajectory of massive capital concentration, colossal data center clusters, and brute-force scaling laws. In the constrained sphere, development pivots toward extreme efficiency, algorithmic compression, localized hardware ecosystems, and heavy state intervention.
This division alters the competitive dynamics of international markets. Domestic Chinese AI firms are compelled to build ecosystems optimized for low-compute environments, inadvertently developing highly efficient models that can operate on edge devices with minimal power consumption. Conversely, Western developers retain an absolute advantage in raw capability scaling, pushing the frontier of foundational intelligence through sheer computational mass.
The strategic reality for participants in this market is uncompromising. Compliance burdens will continue to rise, offshore cloud workarounds will face diminishing returns, and the margin between technological leadership and stagnation will be measured entirely by engineering ingenuity under severe material scarcity.